
A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech Model Hold Up Against Whisper Base? Word Error Rate, Speed, Streaming, Timestamps, Keywords, and Speech-to-Tool Calls on a CPU
MarkTechPosten
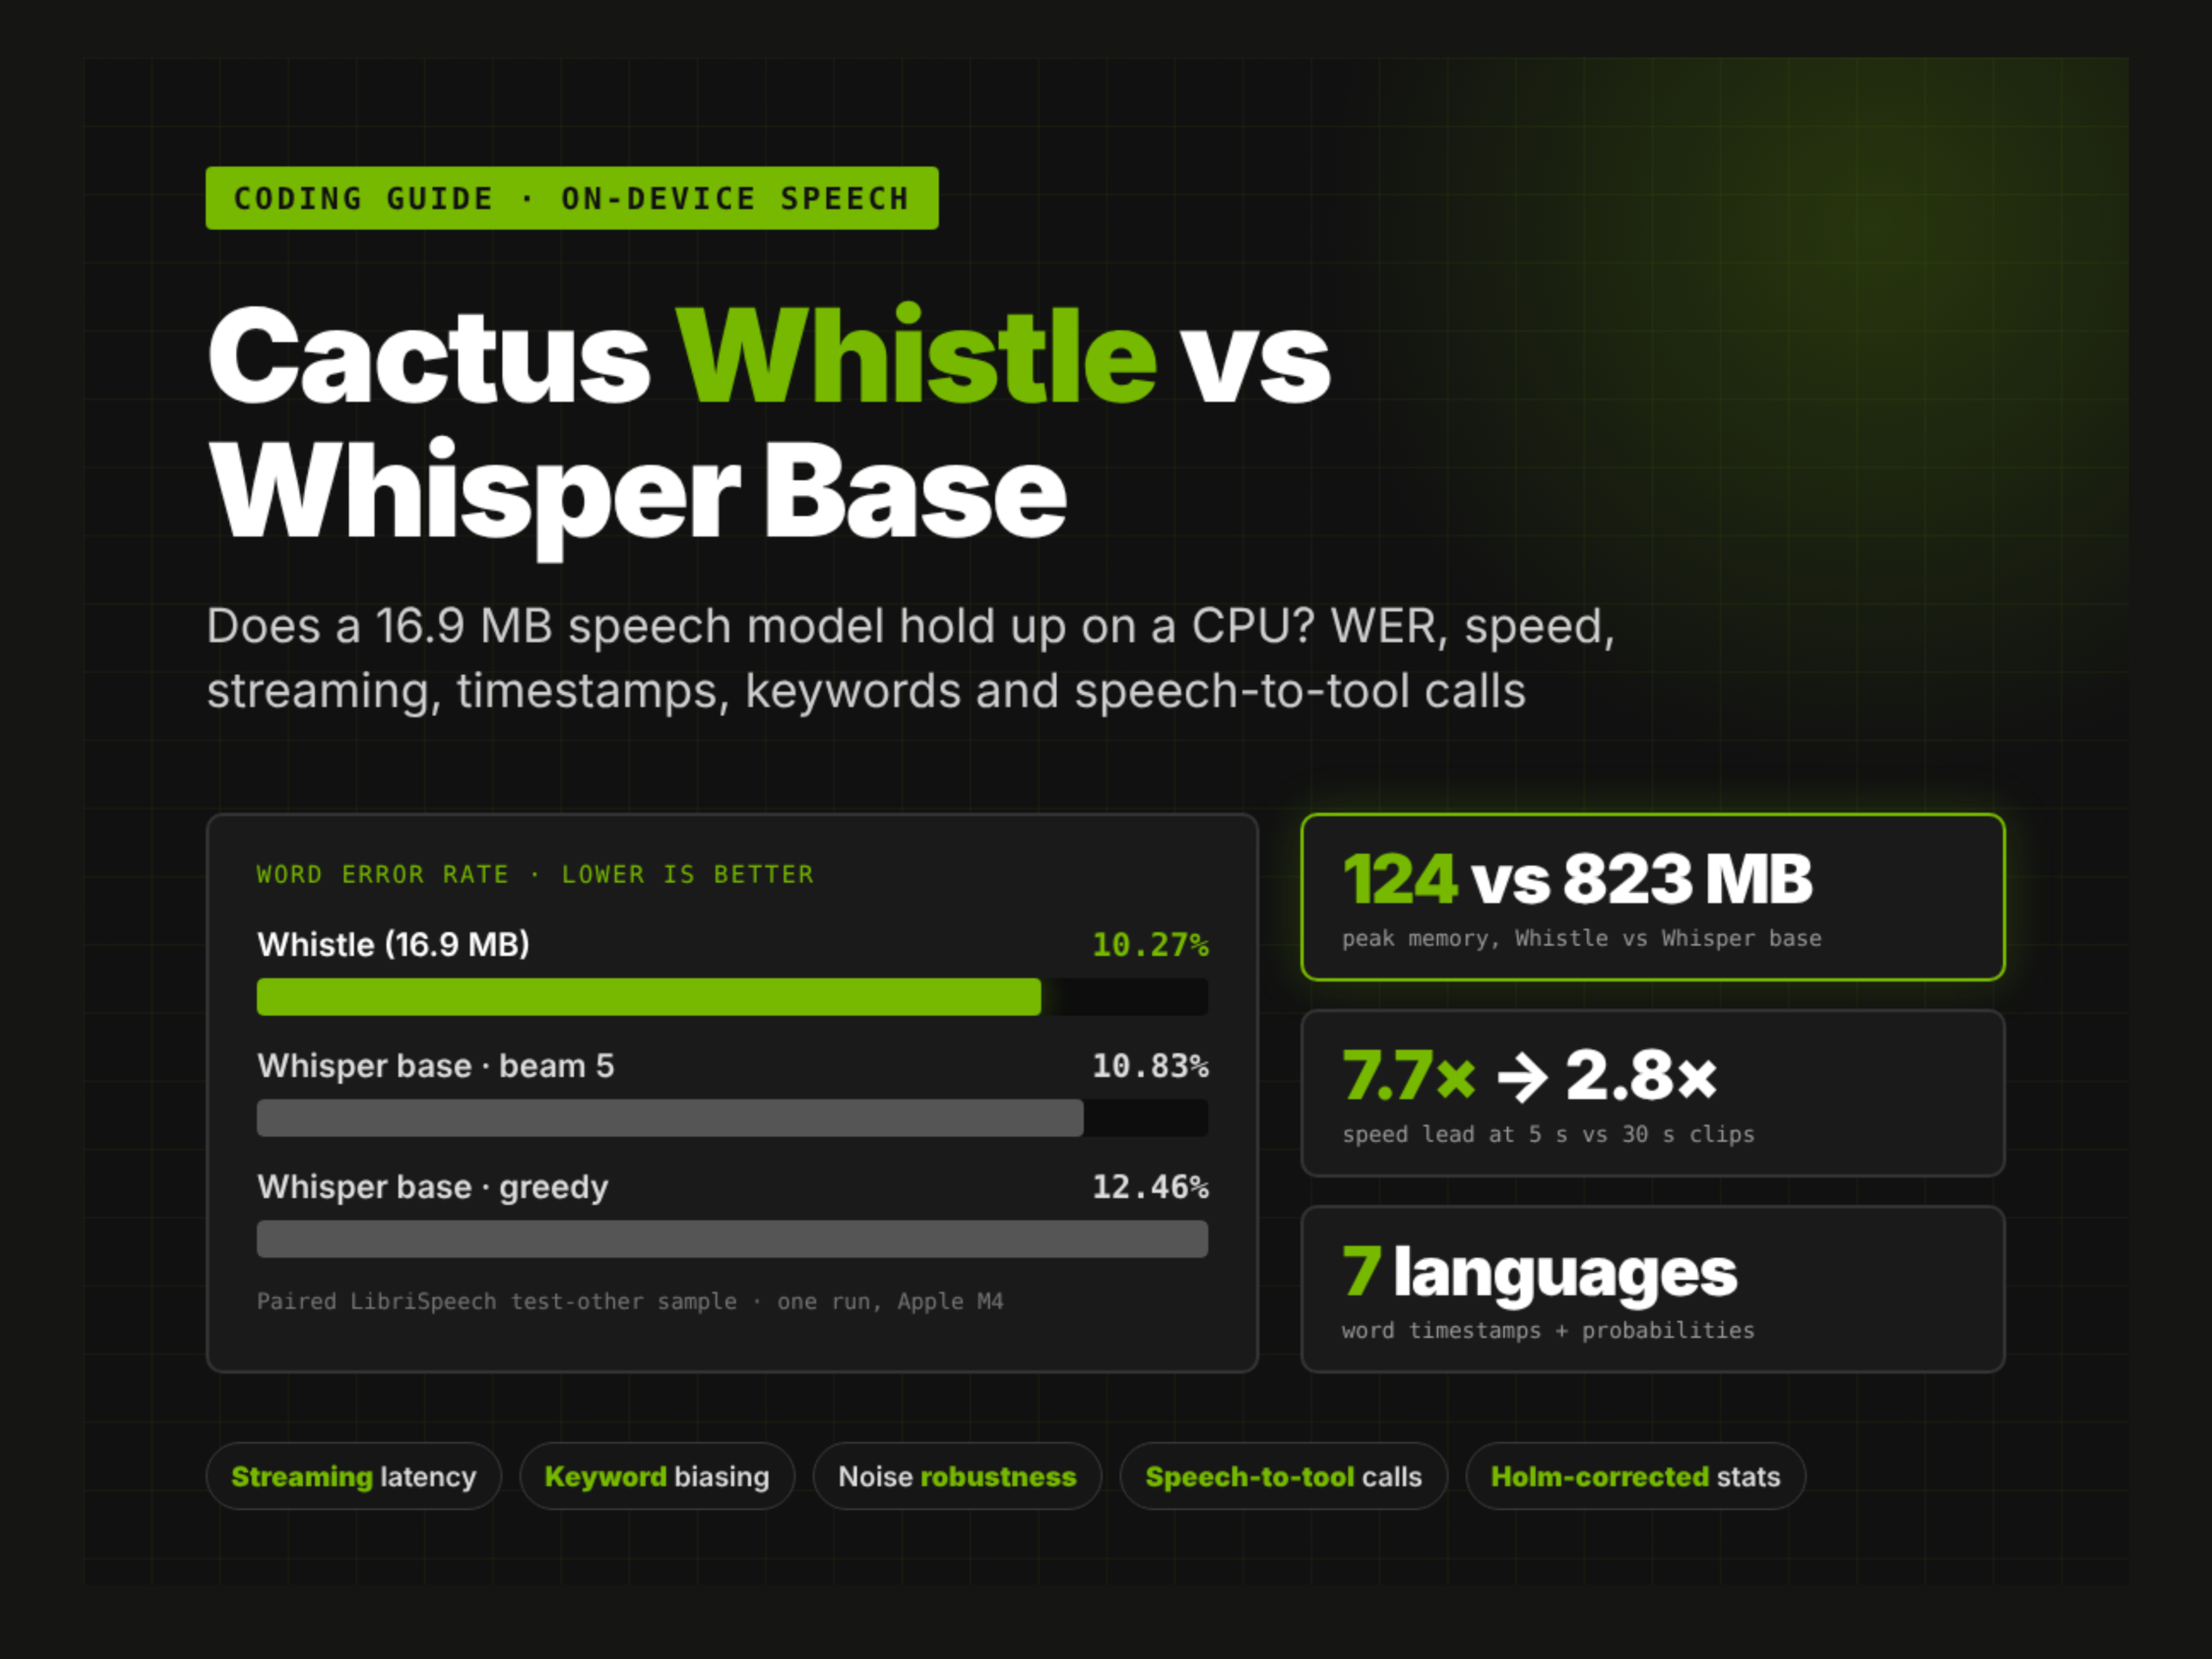
Explore a comprehensive coding guide benchmarking Cactus Compute's 16.9 MB speech model against Whisper base. Learn about word error rates, CPU speed, streaming latency, and speech-to-tool integration. The post A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech Model Hold Up Against Whisper Base? Word Error Rate, Speed, Streaming, Timestamps, Keywords, and Speech-to-Tool Calls on a CPU appeared first on MarkTechPost .
This is a short summary published by AI Global Wire. The full article is owned and hosted by MarkTechPost — open it there to read it in full.
Read the full story at MarkTechPost- Röst-AI
- Verktyg
Related AI news
- Singapore fintech firm Qashier launches AI tools for merchantsTech in Asia · October 22, 2026
- NVIDIA Cosmos Opens New Tools to Train, Evaluate and Deploy World ModelsNVIDIA Blog · October 22, 2026
- Pioneers Across Europe Deploy NVIDIA Earth-2 Open Models to Power Real-World Weather and Climate PredictionNVIDIA Blog · October 22, 2026
- NVIDIA Open Models Power a New Wave of European Public Sector ProjectsNVIDIA Blog · October 22, 2026
- OpenAI acquires Orchestra Bio to advance AI drug developmentDIGITIMES · October 22, 2026
- DiffResearch: Accelerating Deep Research with Diffusion Language ModelsarXiv cs.AI · October 22, 2026