
AI voice and music news
AI audio spans voice cloning, dubbing, speech recognition and full music generation. This page tracks ElevenLabs and Suno releases, new text-to-speech and transcription models, and the licensing fights that follow generated music.
Latest stories

SoundCloud erlaubt direkte Veröffentlichung KI-generierter Musik
Dank ElevenLabs kann man jetzt KI-generierte Musik direkt auf SoundCloud veröffentlichen. Damit wollen beide Dienste den Workflow erleichtern.
heise online – KI
PR Newswire (AI)
AI Global WireNotta Introduces Memo Pro in the U.S. With a Color Display, USB-C and Automatic Wi-Fi Sync
Notta, an AI notetaker and transcription platform, today introduced Notta Memo Pro, the next generation of its portable AI voice recorder, ...
PR Newswire (AI)

ElevenLabs says users can now publish AI-generated music made with ElevenMusic directly on SoundCloud and that users have created 25M+ tracks using its models (Ivan Mehta/TechCrunch)
Ivan Mehta / TechCrunch : ElevenLabs says users can now publish AI-generated music made with ElevenMusic directly on SoundCloud and that users have created 25M+ tracks using its models — Audio AI company ElevenLabs on Thursday said users will be able to publish AI-generated music created using its ElevenMusic platform directly on SoundCloud.
Techmeme
The who’s who of SEA cleantech
Today we explore Southeast Asia’s cleantech landscape and revisit ElevenLabs’ rapid revenue growth as it mulls an IPO.
Tech in Asia
ElevenLabs CEO eyes IPO preparations in 2028
The startup also launched a tool that detects synthetic voices in live audio streams.
Tech in Asia

Sonos adds new Presets and prepares for the 27voice AI beta
Sonos is rolling out a big app update that includes new Presets and early access to its AI voice assistant. You can create a preset to play music at a specific volume in a certain room, which will appear directly on the homescreen so you can quickly start playback. If you're in the US, you […]
The Verge
AWS Machine Learning
AI Global WireBuilding ultra-low-latency voice AI applications on AWS
Learn how Cartesia, an AWS Partner, uses purpose-built State Space Models and AWS infrastructure to deliver sub-100ms text-to-speech and speech-to-text at global scale, and how to deploy its Sonic model on Amazon SageMaker AI or self-managed Amazon EC2 GPU instances.
AWS Machine Learning

AssemblyAI Ships AssemblyAI-TTS-1: A $15 per 1M Character Text-to-Speech API for Voice Agents
AssemblyAI has released AssemblyAI-TTS-1, its first text-to-speech model for voice agents. It costs $15 per 1M characters, offers unlimited concurrency without a contract, and supports 6 languages at launch. The post AssemblyAI Ships AssemblyAI-TTS-1: A $15 per 1M Character Text-to-Speech API for Voice Agents appeared first on MarkTechPost .
MarkTechPost

Nvidia's open Nemotron 3.5 Transcribe combines transcription, translation, and speaker recognition
Nvidia has released Nemotron 3.5 Transcribe, an open speech recognition model that handles transcription, speaker recognition, and translation and takes its instructions as text prompts. It leads several benchmarks and uses only a sixth of the active parameters of its strongest open rival. Nvidia is also shipping a dataset with more than 800,000 hours of speech, along with tools for fine-tuning. The article Nvidia's open Nemotron 3.5 Transcribe combines transcription, translation, and speaker recognition appeared first on The Decoder .
The Decoder
TechCrunch AI
AI Global WireVoice AI in vogue: Nvidia releases new open transcription model
Nvidia just released a free speech-to-text model that can transcribe up to 40 languages, but it only works on recordings, not live audio, so it’s a big step for meeting and medical transcription tools while still leaving real-time use to rivals like ElevenLabs.
TechCrunch AI
TechCrunch AI
AI Global WireDisruptive raises $10B fund to make big bets on at least 10 companies
Disruptive has made headlines in recent years for pouring money into companies like chip startup Groq and the AI voice-generation startup ElevenLabs.
TechCrunch AI

Anthropic stäms för att ha tränat AI-modeller på Elvis-låtar
I fredags valde rättighetsägare till Elvis Presleys musik att lämna in en stämning mot Anthropic rörande brott mot upphovsrätten. Enligt stämningsansökan har Anthropic tränat upp sina AI-modeller på 274 av legendarens sånger utan tillstånd, däribland Can’t Help Falling in Love, Don’t Be Cruel och Return to Sender. – Svaranden har byggt hela sin affärsmodell på upphovsrättsintrång i en omfattning som aldrig tidigare skådats, säger advokaten Richard Busch i ett uttalande. Tidigare har det framför allt varit Suno och liknande tjänster som genererar AI-musik som varit i fokus för den här sortens stämningar, rapporterar Billboard . Anthropic säger i ett uttalande till New York Times att företaget
Computer Sweden
PR Newswire (AI)
AI Global WireSUNON Brings AI, Nature and Human-Centered Design to ORGATEC 2026
SUNON, an international office furniture and workplace solutions brand, will present its latest workplace concepts at ORGATEC 2026, ...
PR Newswire (AI)
arXiv cs.AI
AI Global WireGroup Relative Policy Optimisation Improves Multilingual Speech Recognition in Low-Resource Languages
arXiv:2610.30663v1 Announce Type: new Abstract: Autoregressive encoder-decoder speech recognition models trained with teacher forcing can suffer from exposure bias, limiting their ability to recover from their own prediction errors at inference time. Recent work has shown that reinforcement learning with Group Relative Policy Optimisation (GRPO) improves speech recognition in major languages with LLM-based models. We extend this line of work to smaller, non-LLM encoder-decoder ASR models, using Whisper-large-v3 as a case study across 51 African languages. The benefits of this approach are most pronounced when training data is scarce or when input audio is noisy or degraded. Our resulting mod
arXiv cs.AI
AWS Machine Learning
AI Global WireStream low-latency speech from AI agents using Kokoro TTS on Amazon SageMaker AI
Voice agents often wait for an agent's full response before starting speech synthesis, adding latency users feel directly. This post shows how to stream each sentence to a Kokoro-82M text-to-speech model on Amazon SageMaker AI as the agent produces it, and how to get that audio back to a browser over Server-Sent Events or a unified binary transport.
AWS Machine Learning
Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0
Gradium has open-sourced Phonon, a family of on-device text-to-speech models. The English Phonon 31m ships under Apache 2.0, fits in 64.5 MB, and starts speaking in about 7 ms on a laptop CPU. The post Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0 appeared first on MarkTechPost .
MarkTechPost
AWS Machine Learning
AI Global WireStop guessing auto scaling targets for TTS on Amazon SageMaker AI
Teams deploying custom text-to-speech models on Amazon SageMaker AI often guess at autoscaling thresholds, and a wrong guess either wastes GPU spend or breaches a latency SLO. This post deploys Kokoro-82M as a custom container and derives a measured autoscaling policy from two live-endpoint measurements, Q_max and T_total, instead of guesswork.
AWS Machine Learning
MarkTechPost
AI Global WireIBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation
IBM released Granite Speech 5.0 2B, an Apache 2.0 speech recognition and translation model. It ranks #2 on the Open ASR Leaderboard with 5.68% average English WER, alongside updated Turbo CTC and 4.1 2B Plus models. The post IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and Translation appeared first on MarkTechPost .
MarkTechPost
MarkTechPost
AI Global WireMistral AI Releases Voxtral 3: Speech-to-Text, TTS and a Voice Agent SDK
Mistral AI released Voxtral 3, a family of 3 transcription models, 1 text-to-speech model and a LiveKit-based voice agent SDK. Voxtral Small Transcribe 3 scores 2.1% AA-WER, ranking #3 on Artificial Analysis. The post Mistral AI Releases Voxtral 3: Speech-to-Text, TTS and a Voice Agent SDK appeared first on MarkTechPost .
MarkTechPost

Elevenlabs releases two new speech-to-speech models designed for real-time AI conversations
Elevenlabs' new Eleven Realtime speech-to-speech models combine speed and accuracy. The v1 Max variant scores 98.8 percent on the Big Bench Audio benchmark with a 0.57-second response time. Elevenlabs says no model on the Artificial Analysis leaderboard is both faster and more accurate. The article Elevenlabs releases two new speech-to-speech models designed for real-time AI conversations appeared first on The Decoder .
The Decoder

Scaled Cognition targets customer service with low-cost voice model
Scaled Cognition Inc., an artificial intelligence lab building models for enterprise customer service agents, is introducing a text-to-speech model today that it says provides more accurate pronunciation of account numbers, addresses and other details at a lower cost than competing services. The product, called Voice, is available through an application programming interface or for self-hosted […] The post Scaled Cognition targets customer service with low-cost voice model appeared first on SiliconANGLE .
SiliconANGLE
PR Newswire (AI)
AI Global WireTeleste Introduces an Industry First in Rail Passenger Information with Embedded Acapela AI Voices
Teleste is the first to integrate Acapela's AI text-to-speech technology directly into its proven S-ARRIVE® passenger information ...
PR Newswire (AI)
Analytics India Magazine
AI Global WireKarnataka’s ElevenLabs Partnership Irks Indian Voice AI Startups
Indian voice AI startups worry that giving a formal entry to ElevenLabs and Anthropic could deprive domestic companies of any credibility.
Analytics India Magazine
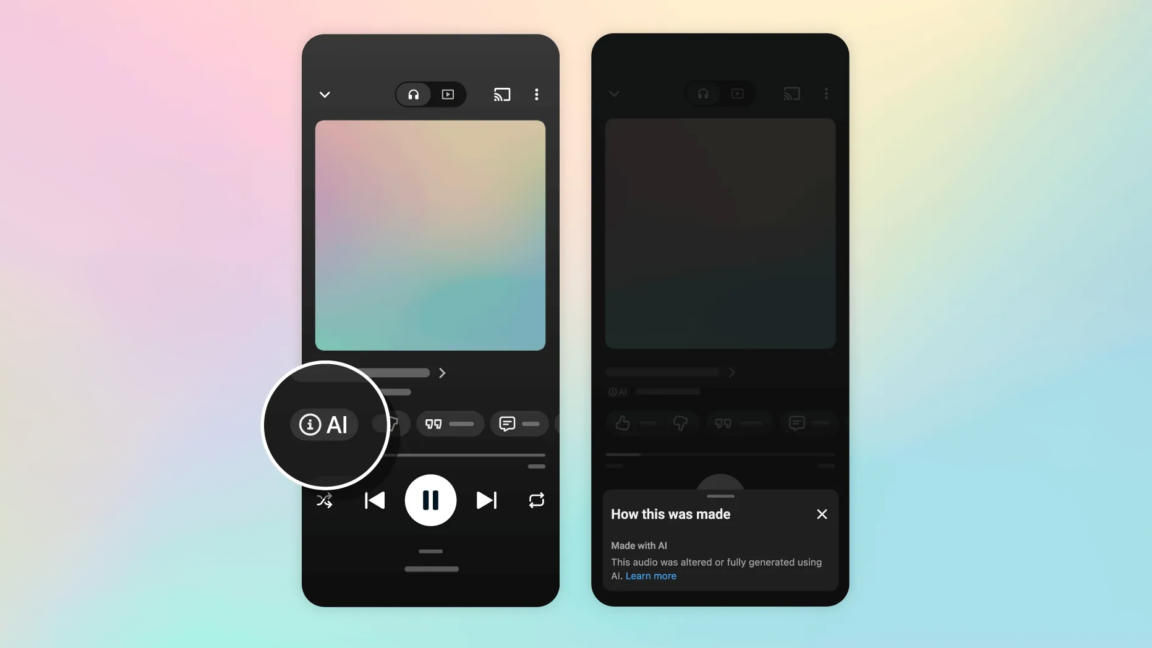
Singer or clanker? YouTube Music will tell you with new gen AI labeling.
The AI music labels are rolling out now in YouTube Music and will come to YouTube soon.
Ars Technica AI

Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on Artificial Analysis
SpaceXAI just released Grok Voice 3.0. Grok Voice 3.0 is a SpaceXAI speech-to-speech model that listens, reasons, calls tools and speaks. It now ranks first on the Artificial Analysis Speech-to-Speech Index with a score of 86.9. For developers, the endpoint, events and $0.08 per minute price are unchanged from Grok Voice 2.0. TL;DR What is […] The post Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on Artificial Analysis appeared first on MarkTechPost .
MarkTechPost
MarkTechPost
AI Global WireFish Audio Releases Drama 3, a 35B Open-Weight MoE Text-to-Speech Model
Fish Audio released Drama 3, a 35B mixture-of-experts text-to-speech model with about 3B active parameters. It takes plain-language direction, covers 83 languages and ships open weights under a revenue-capped community license. The post Fish Audio Releases Drama 3, a 35B Open-Weight MoE Text-to-Speech Model appeared first on MarkTechPost .
MarkTechPost
Analytics India Magazine
AI Global WireSarvam AI Launches Bulbul V4 Flash for Real-Time Speech in 11 Indian Languages
Sarvam AI has launched Bulbul V4 Flash, a text-to-speech model that generates speech in 11 languages with a time-to-first-audio latency of under 250 milliseconds. The model is priced at ₹20 per 10,000 ...
Analytics India Magazine
