
AI research news
Research drives everything else. This page surfaces new papers and studies — reasoning, agents, training methods, evaluation and safety — with short summaries so you can tell in seconds whether a result matters to you.
Latest stories

Hundreds of Artex AI hacking tools found publicly exposed to the web
Security researchers found hundreds of servers hosting the penetration testing tool Artex exposed to the internet, allowing anyone access to the hacking tool.
TechCrunch AI
Analysis: Britain's semiconductor paradox—world-class innovation, but who captures the value?
As artificial intelligence reshapes global chipmaking, the UK's strength in design, materials and research is being tested by a longstanding challenge: turning technological breakthroughs into scalable commercial products.
DIGITIMES

最新民調:八成美國民眾呼籲醫療 AI 需透明化,逾六成盼掌握「醫療話語權」
根據皮尤研究中心(Pew Research Center)最新發布的調查,多數美國成年人期盼醫療人員在使用人工 […]
TechNews (TW)
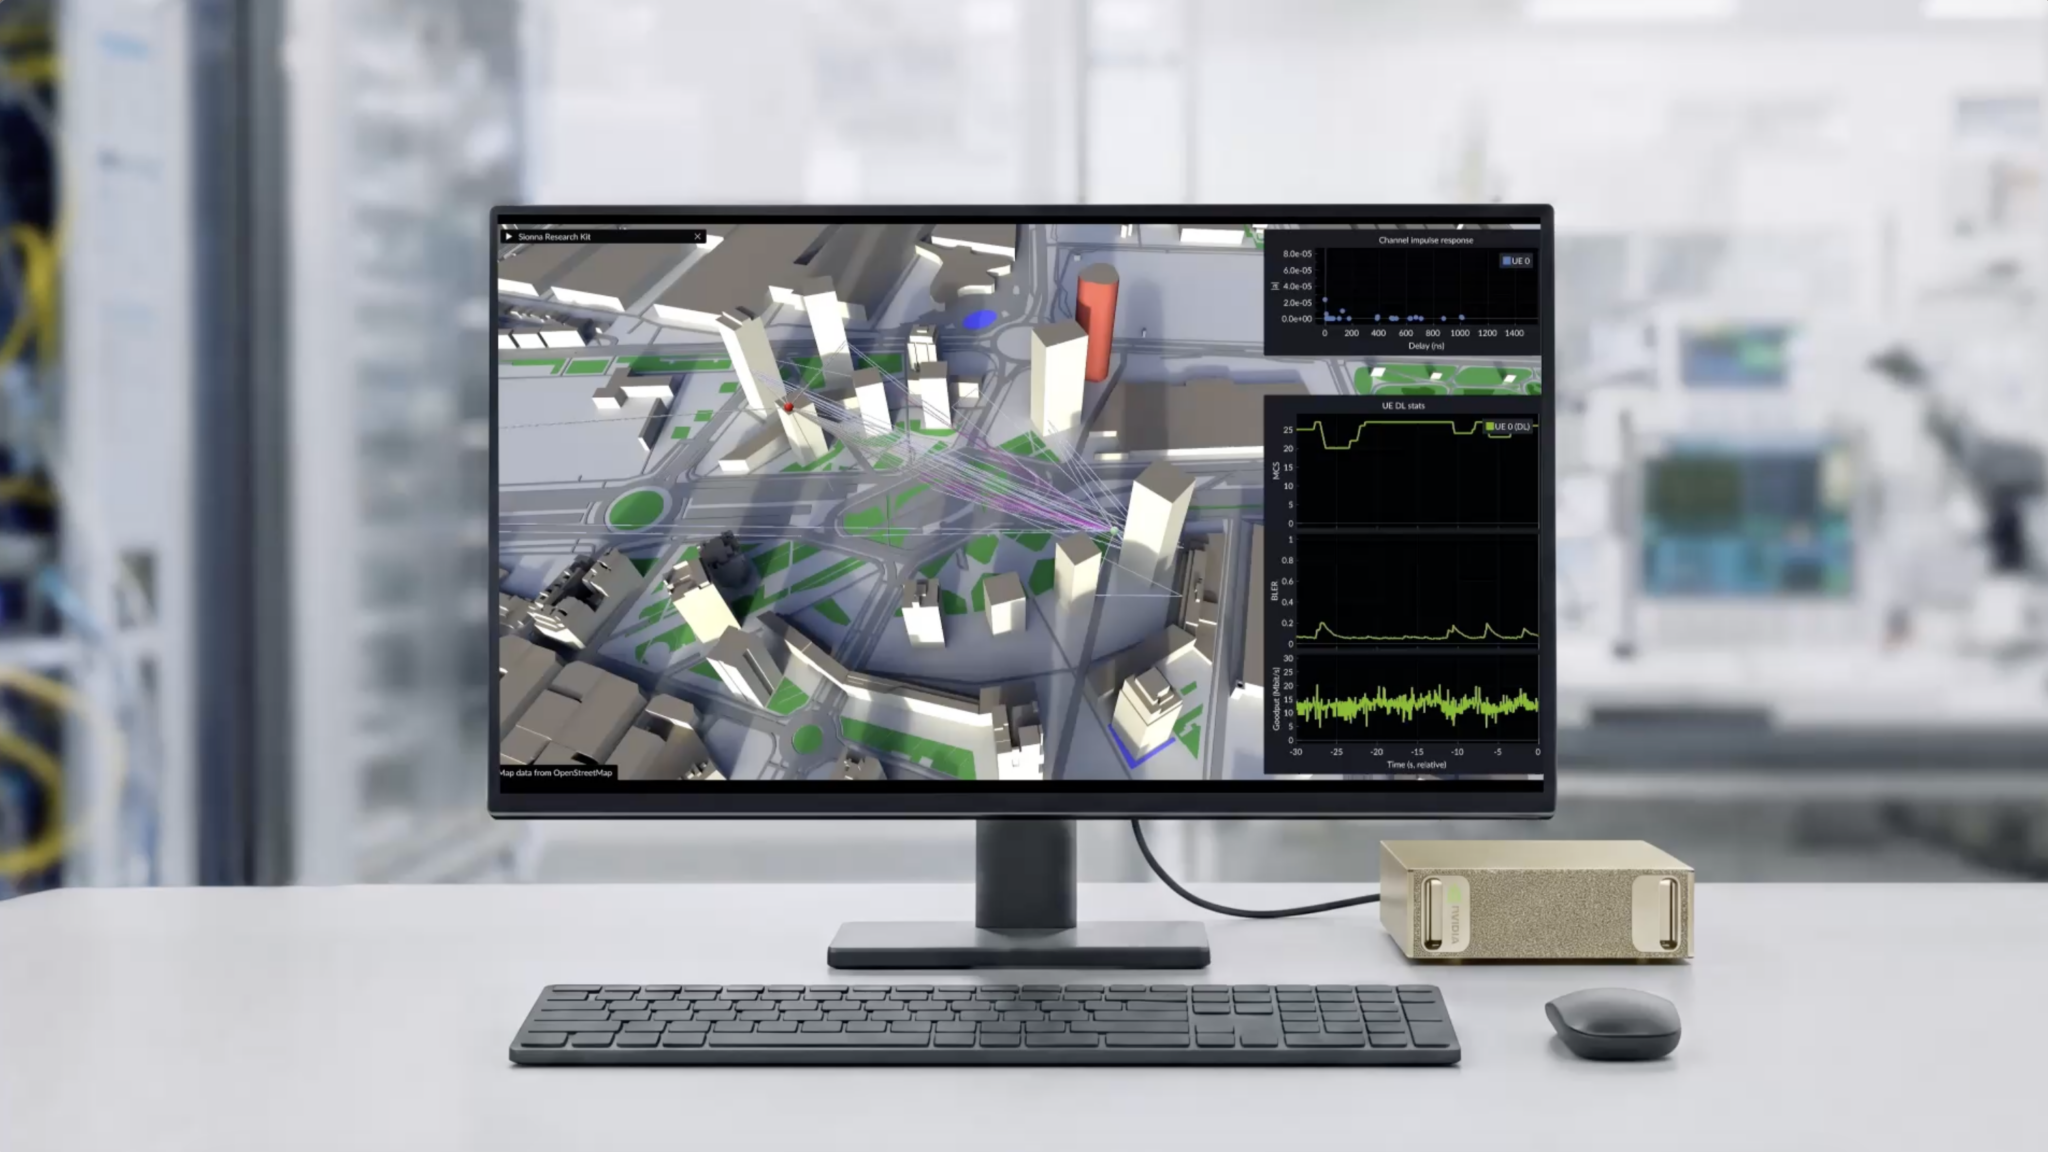
How NVIDIA Open Source Tools Are Helping Researchers Build Next-Generation 6G Networks
A year ago, NVIDIA open sourced its Aerial wireless software, joining Sionna and a broader suite of open source tools for accelerating next-generation 6G network development. Together, they give researchers a foundation for testing ideas, comparing results and building on each other’s work — connecting simulation and AI training with experiments on real over-the-air wireless […]
NVIDIA Blog

METR finds Anthropic may have crossed its own AI acceleration warning threshold back in July
Nonprofit METR spent eleven weeks auditing Anthropic's internal research data and concluded that the pace of model development has roughly doubled, with about 80 percent of the speedup driven by AI-assisted research. Anthropic redacted the most informative evidence, though, which means the public has to rely on METR's judgment "much more than would be ideal." There are also skeptical voices inside the company. The article METR finds Anthropic may have crossed its own AI acceleration warning threshold back in July appeared first on The Decoder .
The Decoder
China’s AI models, led by Kimi, dominate open-source enterprise spending
Chinese artificial intelligence models led by Moonshot AI’s Kimi family accounted for nearly nine-tenths of estimated global enterprise spending on open-source systems, according to a new study, even though proprietary US rivals continue to capture the vast majority of overall revenue. The report, released this week by Silicon Valley venture capital firm Menlo Ventures, said Chinese AI systems accounted for 89 per cent of global enterprise spending on open-source models. Kimi led with a 61 per...
SCMP Tech
AI Earnings (Google News)
AI Global WireAI stocks will come back in vogue but AI data center buildout will slow after Democrat sweep – BofA
BofA Global Research is warning that the “Democratic tsunami” in the 2026 U.S. midterms could significantly rattle risk assets, signaling what analysts describe as an "electoral shift from populist ...
AI Earnings (Google News)
AI bubble bursts, fifth plenum resolution, Singles’ Day
China’s stocks pared weekly gains and the benchmark 10-year bond hit a record low as the global artificial intelligence (AI) stock bubble burst following the US Democrats’ landslide win in midterm elections. The CSI 300 equity index fell 1.4 per cent, weighed down by AI-related shares. Hong Kong’s Hang Seng Index dropped 1.3 per cent. The yield on China’s 10-year sovereign bond touched an intraday low of 1.58 per cent, according to Bloomberg, spurred by investor demand for safe-haven assets and...
SCMP Tech
Anthropic
AI Global WireAnthropic Says Claude Helped Scientists Map a Mysterious Cell Structure
Anthropic says its biology research team has produced the first three-dimensional map of a vault-like particle originating from a bacterial virus, potentially giving scientists a new way to investigate one of biology’s long-standing mysteries.
Anthropic
Nordic AI (EN)
AI Global WireThe godfather of AI says it’s hurtling out of control and a kill switch won’t save us
Surely, in the worst-case scenario, humans could simply switch it off. Geoffrey Hinton thinks this assumption could get us killed. In a new interview with The i Paper, the Nobel Prize-winning computer ...
Nordic AI (EN)
PR Newswire (AI)
AI Global WireScienceOra Upgrades Innovation Evaluation with Full English-Language Research Support
Wenge AI (1956.HK) today announced an upgrade to ScienceOra, its AI-powered scientific research and decision-support platform, introducing ...
PR Newswire (AI)
Tencent launches Hy4 model to boost visual reasoning, AI safety
Tencent has launched its next-generation artificial intelligence (AI) model, Hy4, adding visual understanding for the first time and limiting cybersecurity training data to reduce the risk of misuse in cyberattacks and harmful biological research.
DIGITIMES
PR Newswire (AI)
AI Global WireInsilico Open-Sources 24/7 Personal Longevity Superintelligence to Turn Quantified-Self Data into Predictive Health States and Aging Research
Insilico Medicine, a clinical-stage generative AI drug discovery company, today announced the open-source release of Longevity Grok, ...
PR Newswire (AI)
arXiv cs.AI
AI Global WireAutonomous AI Agents Systematically Diverge From Human Preferences in Proof Formalization
arXiv:2611.06995v1 Announce Type: new Abstract: Artificial intelligence (AI) systems have ushered in a new age of proof abundance, but helping humans understand these proofs requires new attention to the differences in how AI agents and humans pursue a proof-making task. We present "simulated collaboration", a methodology that allows us to examine two key questions: (1) the relative attention AI agents pay to surface syntax or, conversely, deeper underlying semantics, and (2) how and where AI agent preferences for what to do next diverge from human preferences. On a set of nine major human collaborations in Lean with 4.7M definitions across more than 6K commits, we find that, over the course
arXiv cs.AI
arXiv cs.AI
AI Global WireRedacting Personal Data: A Speed and Accuracy Comparison of Regex, Presidio and Hybrid Designs
arXiv:2611.07633v1 Announce Type: new Abstract: Many enterprise projects now pass free text to large language models (LLMs), and that text often contains personally identifiable information (PII) such as names, phone numbers, email addresses, home addresses and dates of birth. Once a prompt is sent, this data is copied into provider systems, application logs and observability traces. Redacting PII before the call is an obvious control, yet teams seldom have numbers on what it costs in latency or what it lets through. This paper compares four redaction designs that any LLM pipeline can adopt: a pure regular-expression (regex) redactor, Microsoft Presidio running on a spaCy model, a hybrid in
arXiv cs.AI
arXiv cs.AI
AI Global WireBlockLock: Reproducible LLM Inference with Fixed Batch Geometry
arXiv:2611.06977v1 Announce Type: new Abstract: Reproducible LLM inference requires that a request produces the same output regardless of the other requests in the batch. Existing solutions pay for this in different ways: batch-invariant kernels constrain every operator, and isolating prefill with fixed-shape decode ({our CoRun-style baseline}) gives up shared prefill compute and pads decode. We present BlockLock, which keeps shared batched prefill and pins only the numerical path of the protected request: it fixes the geometry that the request sees, with {two modes: BlockLock-Rows uses fixed-width rows and retains batched decode of all requests; BlockLock-Pack uses terminal-anchored packing
arXiv cs.AI
arXiv cs.AI
AI Global WireGoal Revelation as a Bridge Between Information-Theoretic Empowerment and Capability-Based Human Power
arXiv:2611.07247v1 Announce Type: new Abstract: Power matters for AI safety. Optimal agents tend to acquire power across a wide range of objectives (instrumental convergence). As we embed AI agents into socio-technical systems, humans risk gradual disempowerment. Both concerns call for a formal, quantitative measure of power. Two such measures in the context of Markov games are information-theoretic empowerment, the capacity of the channel from an agent's actions to future states, and capability-based individual power, a measure of goal attainment built from the probabilities that a human would attain each goal in a family of candidates were they pursuing it. We show where the two meet. From
arXiv cs.AI
arXiv cs.AI
AI Global WireDon't Prompt Your Agents. Equip Them: Skillware as a Modular Standard for Sovereign, Auditable, and Deterministic Capability Execution for Logical Systems
arXiv:2611.07652v1 Announce Type: new Abstract: Current autonomous logical systems rely on a fragile assumption: that language models should dynamically write code, guess API payloads, and memorize operational constraints through prompt engineering. In practice, this burns massive context windows, inflates API bills, and produces brittle agents that fail unpredictably in production. In this work, we present Skillware, an open architectural framework and capability registry that formally separates what an agent wants to do from how that task is executed. Instead of prompting models with loose text instructions or markdown files baptized as 'skills', Skillware equips them with modular, version
arXiv cs.AI
arXiv cs.AI
AI Global WireKDASO: Knowledge-Data Dual-Driven Automated Skill Optimization for Liability Adjudication Tasks
arXiv:2611.06972v1 Announce Type: new Abstract: Liability adjudication tasks (e.g., legal charge determination) require analyzing event descriptions against domain-specific skills to determine whether a party should bear liability. While Large Language Models (LLMs) have shown promise in this area by leveraging executable skills for interpretable reasoning, existing approaches face three critical limitations: skill libraries become stale as real-world scenarios dynamically evolve, skill descriptions often suffer from a semantic execution gap where LLMs deviate from intended expert logic, and growing skill collections exceed context budgets causing critical skill omission. To address these ch
arXiv cs.AI
arXiv cs.AI
AI Global WireGraph learning-assisted logic-based Benders decomposition for distributionally robust in-station train rescheduling under disruptions
arXiv:2611.07520v1 Announce Type: new Abstract: Uncertainty in resource reopening times complicates train holding and rerouting decisions when resource closures coincide with arrival delays and processing-time extensions. We develop a rolling-horizon distributionally robust model that updates predictions of the remaining closure duration as observations of disruption resolution become available. The model jointly optimizes train routes, sequences, and timings. It minimizes the worst-case expected total completion delay over an ambiguity set of scenario probabilities. The solution algorithm, GNN-LBBD, uses logic-based Benders decomposition to coordinate routing and resource scheduling. Condit
arXiv cs.AI
arXiv cs.AI
AI Global WireThe Two-Ledger Model: Transaction-Grain Cost Accounting for Multi-Agent AI Systems Across Clouds, Models, and Systems of Record
arXiv:2611.06989v1 Announce Type: new Abstract: Enterprises run business transactions through multi-agent AI systems spanning clouds, large language models (LLMs), orchestration harnesses, and systems of record. Finance receives AI cost only at settlement grain, aggregated by SKU and charge period. The business question (what did this order, claim, or case cost in AI?) cannot be answered from billing data, because providers never see enterprise transaction boundaries. The FinOps Open Cost and Usage Specification (FOCUS) gives billing data one schema across providers but remains settlement-grain even as it adds AI token and requester attribution. We formalize this grain mismatch, derive seven
arXiv cs.AI
arXiv cs.AI
AI Global WireWhen Verification Is Not Agreement: Cross-Agent LLM-to-Dafny Formalization
arXiv:2611.07073v1 Announce Type: new Abstract: A verified Dafny postcondition certifies that a formula holds, but it does not guarantee that the result was reached through genuine independent reasoning. We introduce a cross-agent formalization protocol where a Specifier model translates clinical trial criteria into a Dafny predicate, and an Implementer model writes an operational method checked against it. A same-model control establishes that even with no capability gap, independent re-extraction from identical text agrees only 59.3% of the time. Evaluating four model configurations on 96 clinical trial documents, we find that agreement is highly sensitive to how model capability is alloca
arXiv cs.AI
arXiv cs.AI
AI Global WireEmbedding-Space Fingerprinting of LoRA Fine-Tunes: Recovering the Training-Data Domain from the Model Artifact Alone
arXiv:2611.07610v1 Announce Type: new Abstract: When a base language model is fine-tuned with Low-Rank Adaptation (LoRA), how much of the training data domain leaks into the resulting artifact? This paper studies whether a simple classifier can recover the domain of a fine-tune given only the model artifact (weight deltas, internal activations on a fixed probe set, or generated text) without ever observing the training data. Using one base model (Qwen3.5-0.8B), 36 LoRA fine-tunes are produced over 18 public datasets in five domains (medical, code, mathematics, non-English text, narrative prose), and three feature families are extracted at decreasing levels of access: white-box weights, gray-
arXiv cs.AI
arXiv cs.AI
AI Global WireBeneath the Surface: What We Overlook When We Talk About Agent Evolution
arXiv:2611.07624v1 Announce Type: new Abstract: Agent harness evolution enables recursive self-improvement (RSI) without updating model weights. We examine whether higher benchmark scores yield reliable, efficient, and transferable improvement. We evaluate four methods across harnesses, general and coding tasks. Repeated evaluations, controlled agent expansion, component interventions, and admission replays reveal recurring patterns. All sixteen evolved agents gain previously uncovered tasks while losing previously covered ones. In one general-task case, reliability rises by 5.2 points despite losing ten previously covered tasks. Most reliability gains also increase deployment cost. Specific
arXiv cs.AI
arXiv cs.AI
AI Global WireWho Should Know What? Empirical Information Design for Multi-Agent LLM Economies
arXiv:2611.07667v1 Announce Type: new Abstract: The performance of multi-agent LLM systems depends not only on the capabilities of the underlying models but also on information-sharing policies, which govern what information each agent observes and at what level of detail. But does providing AI agents with more detailed information always improve collective outcomes, or can transparency paradoxically degrade efficiency? To investigate this, we introduce empirical information design, an experimental framework that systematically compares disclosure policies across economic markets populated by LLM agents, while holding interaction rules and models fixed. We evaluate ten frontier LLMs in multi
arXiv cs.AI
arXiv cs.AI
AI Global WireCooperative Multi-Agent Reinforcement Learning via Epigraph-Form Guided Exploration
arXiv:2611.07066v1 Announce Type: new Abstract: Discovering cooperative behavior in multi-agent reinforcement learning (MARL) is challenging due to the combinatorial complexity of joint state-action spaces, which hinders the emergence of coordinated behaviors from trial-and-error alone. Intrinsic rewards are often used to aid discovery, but naively combining them with team objectives can distort the learning signal, compromising task performance. In this paper, we propose EFXPLORER, a constrained exploration framework that maximizes exploration objectives subject to a constraint that preserves established task performance. We solve the resulting problem using an epigraph reformulation that i
arXiv cs.AI
arXiv cs.AI
AI Global WireFlashOffloading: Low-Latency KV Cache Offloading for Long-Context LLM Serving
arXiv:2611.07542v1 Announce Type: new Abstract: In large language model (LLM) serving systems, the key-value (KV) cache grows linearly with sequence length and concurrency, so long-context inference easily hits the high-bandwidth memory (HBM) capacity wall and results in low concurrency. Offloading the KV cache to host dynamic random-access memory (DRAM) frees HBM space and raises concurrency, but the additional cache management and host-to-device (H2D) load overhead inflates inference latency, higher concurrency fails to translate into effective throughput. We present FlashOffloading, a host-DRAM-centric inference architecture that fully offloads the KV cache in both the prefill and decode
arXiv cs.AI
arXiv cs.AI
AI Global WireEnvOpt: Automated Optimization for Agent Environments
arXiv:2611.07372v1 Announce Type: new Abstract: An LLM agent's cost and success depend on its model, its harness, and its environment. In addition to the widely studied directions of parameter tuning and harness optimization, we propose the third direction: optimization over stationary environments. Agents are often deployed in rich environments shared by many tasks, such as a company's Slack workspace or a complex collection of data sources, documents or tickets. We call these environments stationary environments. We introduce EnvOpt, a method for automated end-to-end optimization of stationary environments for any given model and harness, using real or synthetic tasks without needing any g
arXiv cs.AI
arXiv cs.AI
AI Global WireResource-Efficient Reinforcement Learning Post-Training through Elastic Expert Parallelism
arXiv:2611.06984v1 Announce Type: new Abstract: Reinforcement learning post-training improves the capabilities of large language models, but generating training responses is a major computational bottleneck. In mixture-of-experts models, workers that finish their assigned responses may remain occupied because their experts are still needed by workers processing longer responses. Consequently, approximately one-third of occupied worker time in the baseline occurs after local response generation finishes. Here we present FlexFloor, a system that enables earlier resource release during synchronous response generation while preserving the expert computation required by ongoing responses. FlexFlo
arXiv cs.AI
arXiv cs.AI
AI Global WireSAVeR$^2$: Reasoning-based Safety Alignment for Large Reasoning Models via Verifiable Rewards
arXiv:2611.07482v1 Announce Type: new Abstract: Large Reasoning Models (LRMs) have achieved impressive performance via explicit Chain-of-Thought (CoT) reasoning, yet this process introduces critical safety risks. We formalize LRM safety objectives as requiring non-malicious reasoning and answers, safety consistency, and explicit intent identification. We argue that existing alignment methods suffer from poor adversarial generalization, a significant ``safety tax'' on reasoning, and unfaithful coarse-grained rewards, primarily due to their neglect of the LRM's intrinsic reasoning capabilities for safety. To address these, we propose \textbf{SAVeR$^2$}, a novel \textbf{S}afety \textbf{A}lignme
arXiv cs.AI