
Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms LFMs
MarkTechPosten
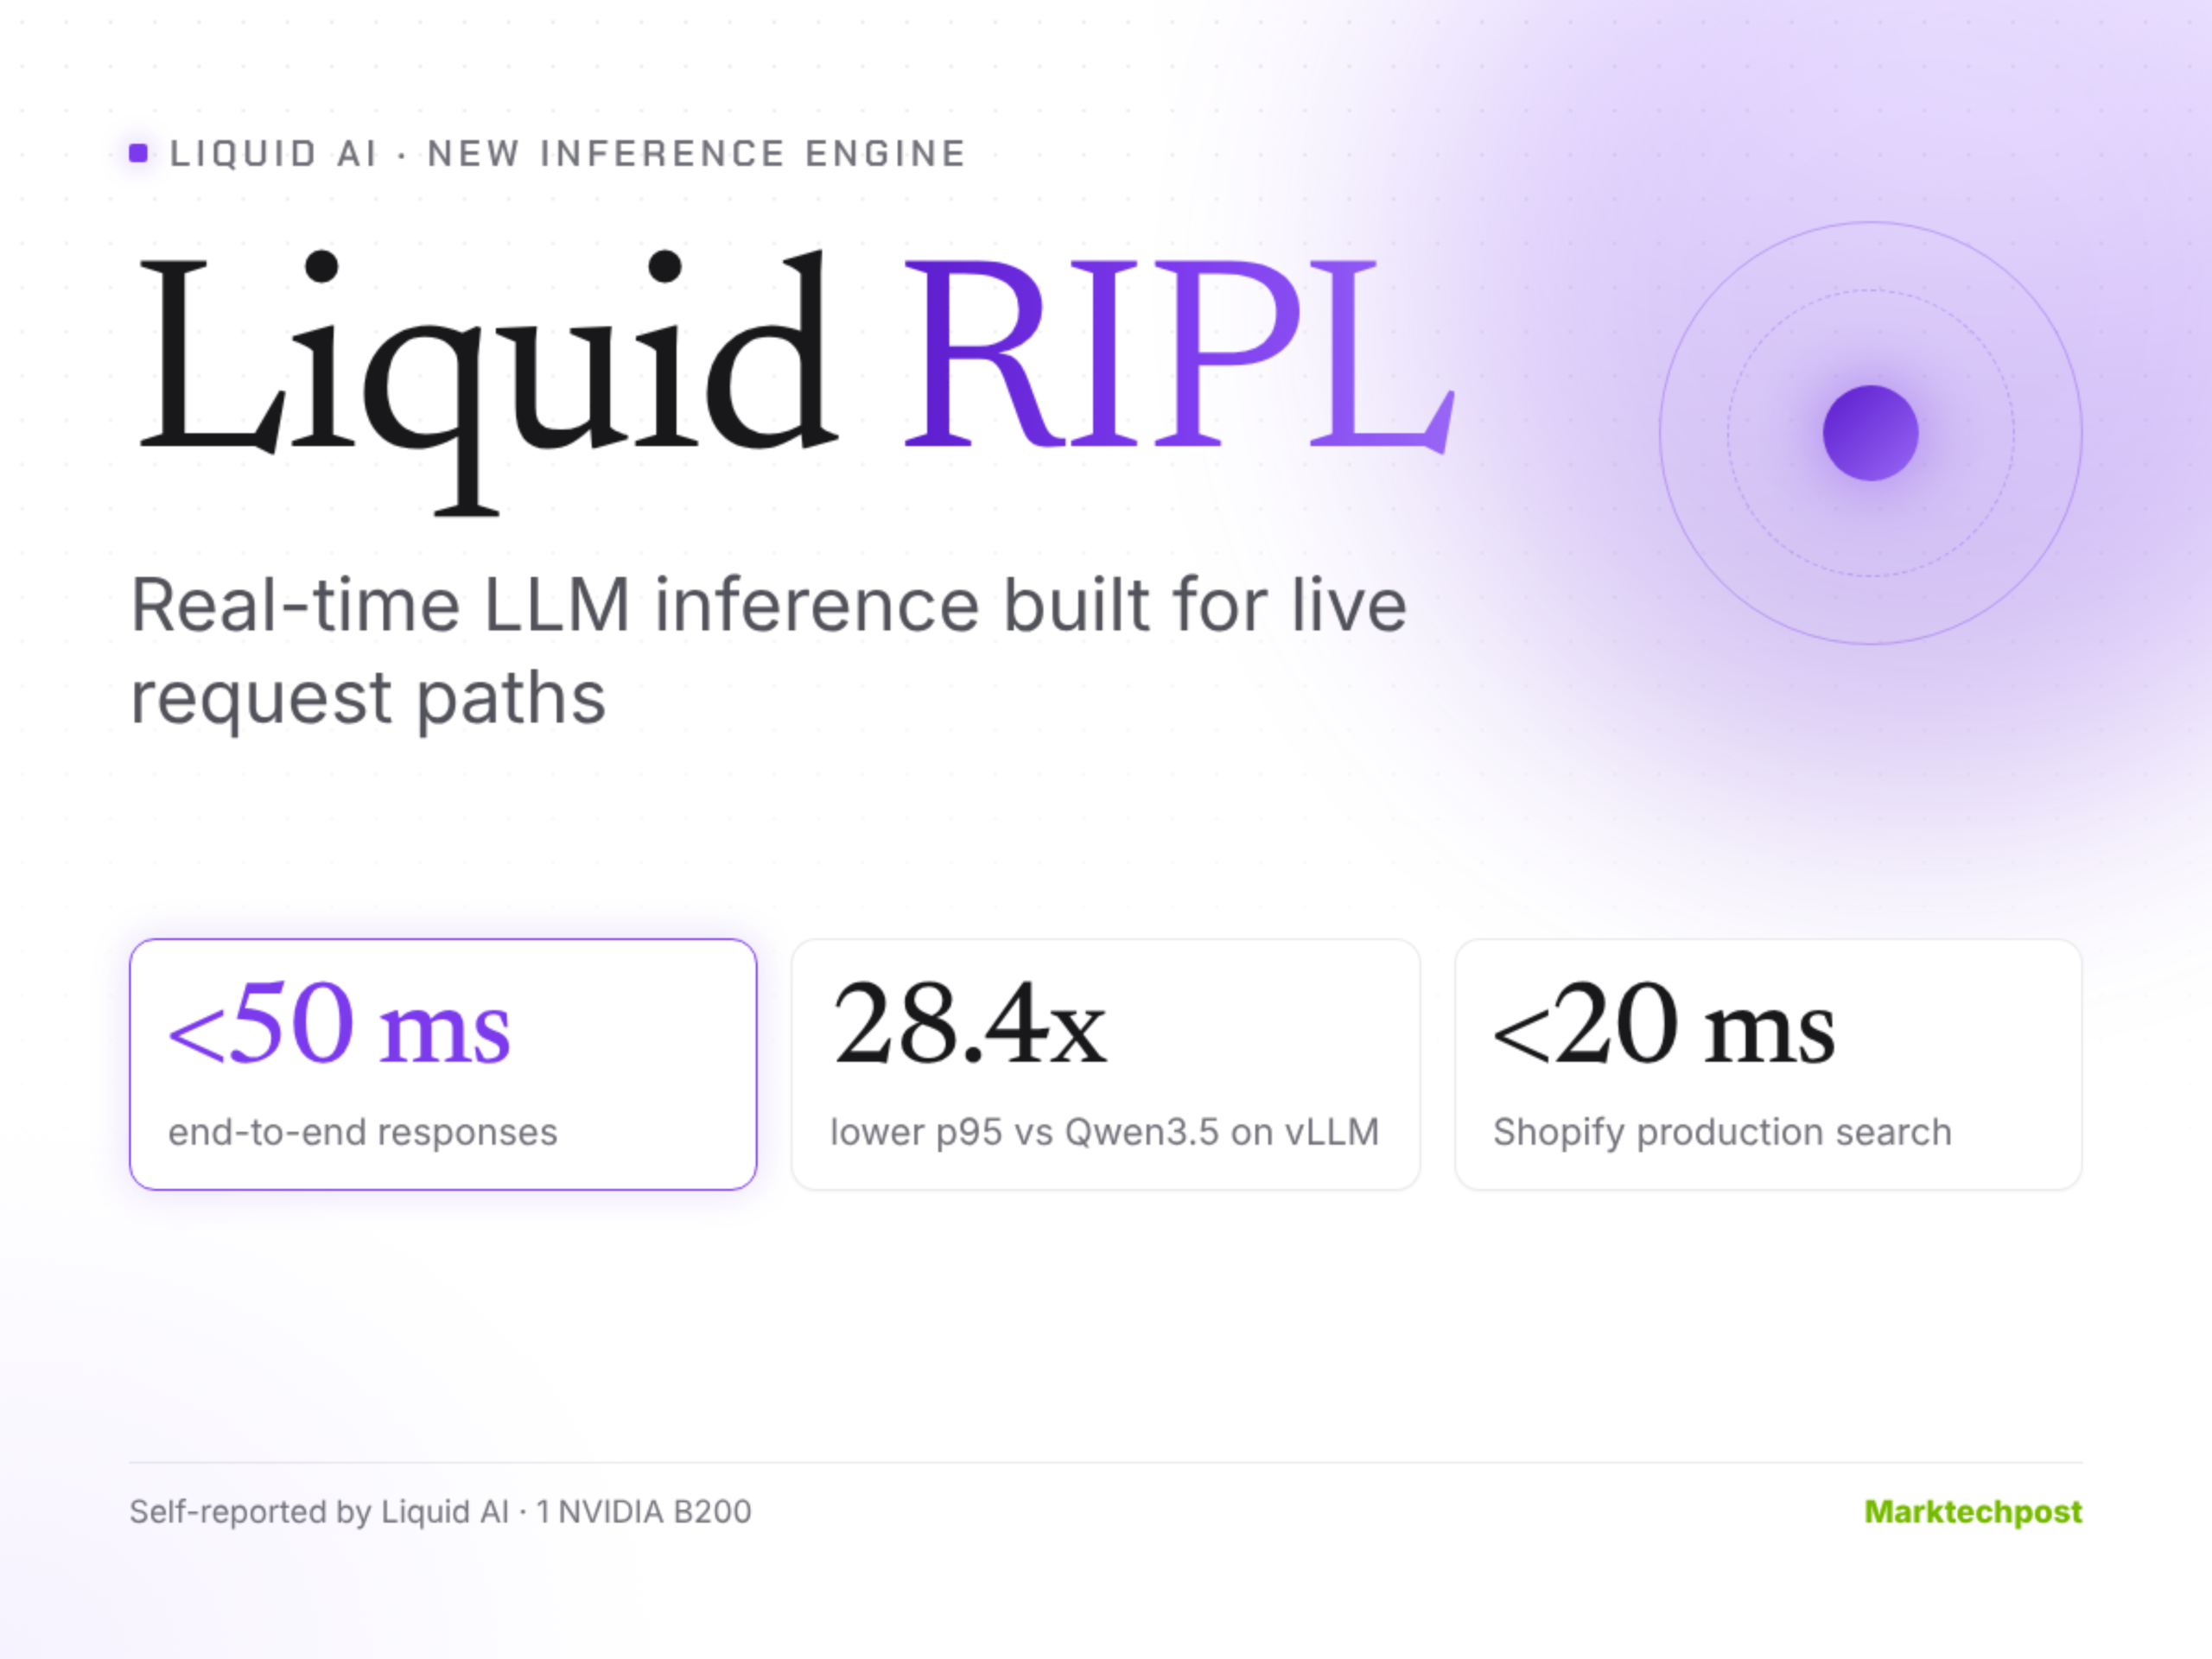
Liquid AI released RIPL, a real-time inference engine for its LFM models. On one B200, LFM2.5-1.2B on RIPL showed 14.4 to 28.4x lower p95 latency than Qwen3.5-0.8B on vLLM. The post Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms LFMs appeared first on MarkTechPost .
This is a short summary published by AI Global Wire. The full article is owned and hosted by MarkTechPost — open it there to read it in full.
Read the full story at MarkTechPost- Verktyg
Related AI news
- Major US banks are locking out AI agents that log in with customer credentialsThe Decoder · October 22, 2026
- Microsoft says its AI tool is better than doctors at diagnosing conditionsThe Verge AI · October 22, 2026
- Google's Agent Compute Engine gives every Gemini agent its own hardware-isolated micro virtual machineThe Decoder · October 22, 2026
- Deploy AI in a HIPAA-eligible environment with Amazon QuickAWS Machine Learning · October 22, 2026
- Anthropic rolls out Claude Duet, but enterprises aren’t readyAI Business · October 22, 2026
- Nirva raises $25M to make AI jewelry with ‘perspective’ that listens and provides insightsSiliconANGLE · October 22, 2026