
NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5%
MarkTechPosten
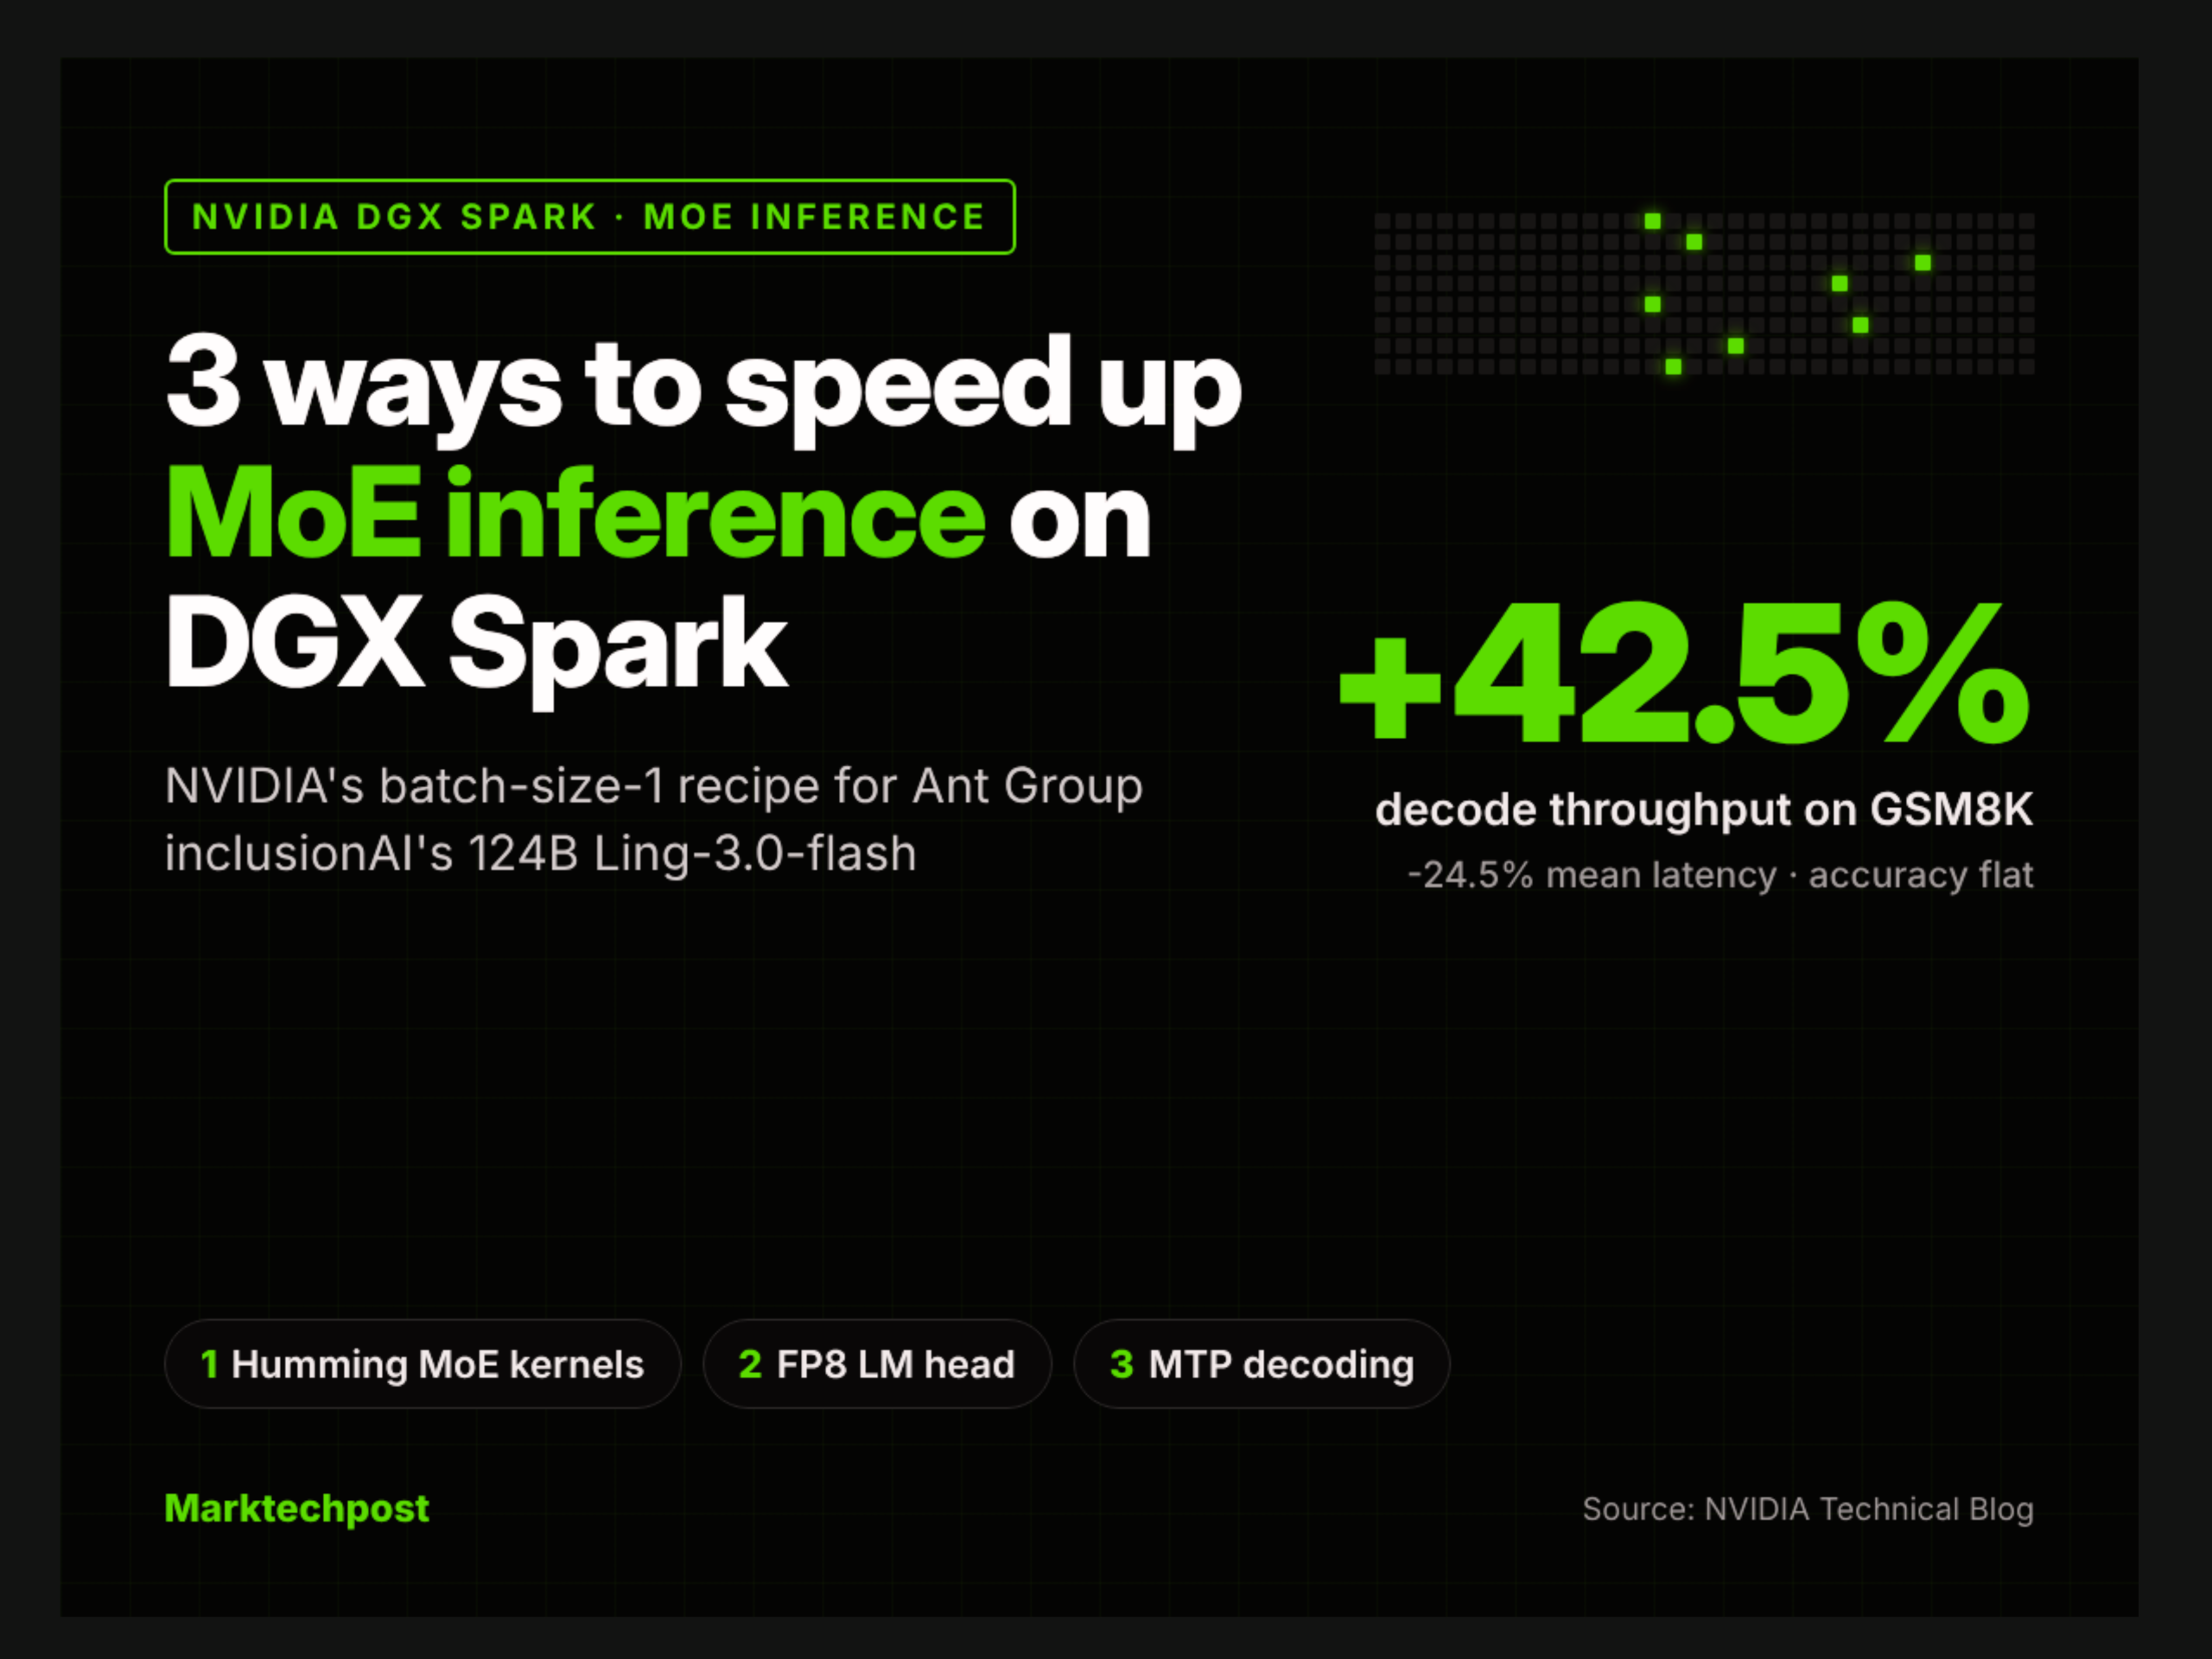
NVIDIA shows how 3 stacked optimizations speed up MoE inference on a single DGX Spark. On Ant Group inclusionAI's 124B Ling-3.0-flash, GSM8K decode throughput rose 42.5% with no detectable accuracy change. The post NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5% appeared first on MarkTechPost .
This is a short summary published by AI Global Wire. The full article is owned and hosted by MarkTechPost — open it there to read it in full.
Read the full story at MarkTechPost- Verktyg
Related AI news
- Sonos adds new Presets and prepares for the 27voice AI betaThe Verge · November 3, 2026
- Binance says hackers used fake job interviews and an internal AI tool to pull off the $6.3 billion heistThe Verge · November 3, 2026
- Revolut says it cut AI coding inference costs by ~90% in less than a year by making self-hosted GLM models its default over commercial tools like Claude Code (Tobias Mann/The Register)Techmeme · November 3, 2026
- Salesforce to buy customer service automation startup Cresta for reported $2.7BSiliconANGLE · November 3, 2026
- Anthropic releases FlashProve, open-source code that cryptographically verifies an AI response came from a given model, not a cheaper one swapped in by a router (Anthropic)Techmeme · November 3, 2026
- Anthropic releases FlashProve, an open-source prototype that cryptographically verifies an AI response came from a given model, not one that a router swapped in (Anthropic)Techmeme · November 3, 2026